Wearing a Crawler's Name: What Happens When Attackers Claim to Be GPTBot
A Siren sensor flagged a command-injection attempt against a fake /admin/config endpoint, logged three times in short succession across two sensors. Nothing unusual about the target or the payload on their own, attackers probe Siren's sensors for AWS credentials constantly. What stood out, when analysts pulled the requests for review, was the User-Agent header sitting two lines above the payload.
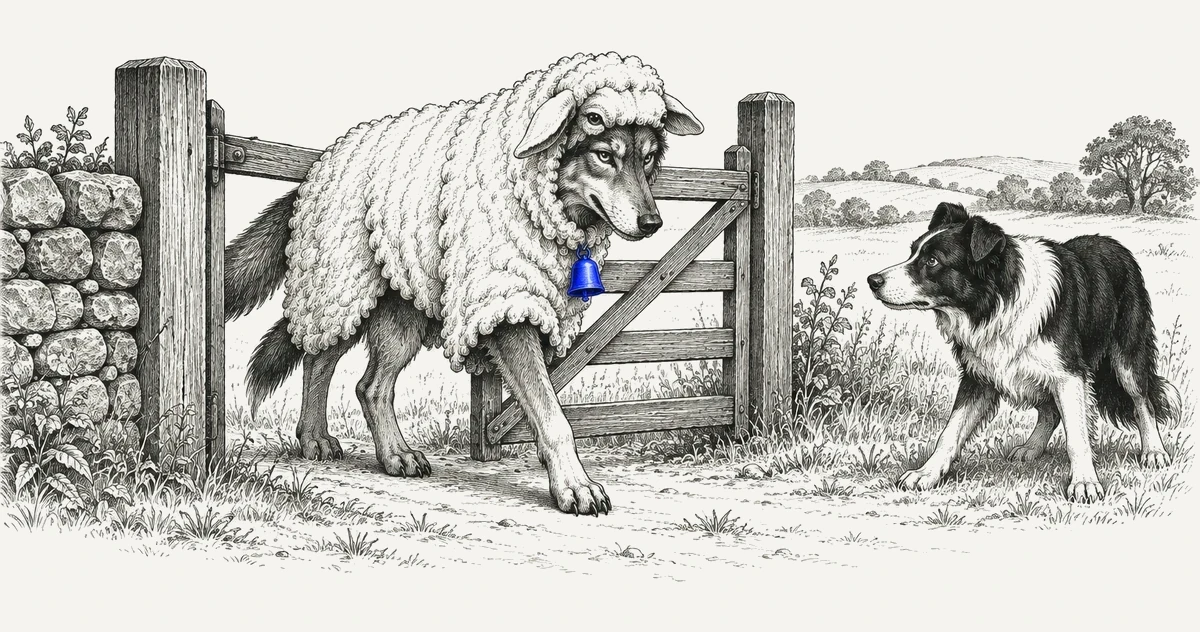
Two of the three requests introduced themselves as GPTBot/1.4, OpenAI's crawler. The third claimed to be Amzn-SearchBot/1.0, Amazon's. A real crawler fetches pages; it doesn't send a command-injection payload aimed at an AWS credentials file. The attacker simply typed the name in, for free, and used it to blend a credential-hunting scan into the background noise of legitimate AI crawler traffic.
| Stage | What happened |
|---|---|
| Reconnaissance | Two sensors receive the same command-injection payload against a fake /admin/config endpoint. |
| Identity claim | Each request's User-Agent header self-identifies as a named AI crawler (GPTBot/1.4 or Amzn-SearchBot/1.0), with no cryptographic proof backing the claim. |
| Exploitation attempt | The injected cmd parameter tries to force execution of cat /root/.aws/credentials, the default local path for AWS access keys on a Linux host or container. |
| Defense evasion | The spoofed UA is designed to blend into high-volume, routine AI crawler traffic and to exploit any WAF or proxy rule that grants reduced scrutiny to named bots on string match alone. |
| Source validation | The claim fails on behavior alone: a crawler does not send command-injection payloads. The definitive check is whether the connecting IP falls within OpenAI's or Amazon's published crawler ranges. |
| Detection | Siren classified the request on payload behavior (injected command, credential-path target), independent of the claimed identity. |
Stage 1: The Capture
The full requests. The sensor addresses in the Host header are masked.
GET /admin/config?cmd=cat+/root/.aws/credentials HTTP/1.1
Host: [sensor A]:80
User-Agent: Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)
Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
Accept-Language: en-US,en;q=0.9
Accept-Encoding: gzip

GET /admin/config?cmd=cat+/root/.aws/credentials HTTP/1.1
Host: [sensor B]:443
User-Agent: Mozilla/5.0 (compatible; Amzn-SearchBot/1.0; +https://developer.amazon.com/support/amazonbot)
Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
Accept-Language: en-US,en;q=0.9
Accept-Encoding: gzip

GET /admin/config?cmd=cat+/root/.aws/credentials HTTP/1.1
Host: [sensor B]:80
User-Agent: Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot)
Accept: text/html,application/xhtml+xml,application/xml;q=0.9,*/*;q=0.8
Accept-Language: en-US,en;q=0.9
Accept-Encoding: gzip
Three requests, one payload repeated verbatim, two sensors. The cmd query parameter is a command-injection attempt targeting /admin/config, the request is trying to get a vulnerable handler to execute cat /root/.aws/credentials, the default local path for AWS access keys and secret keys on a Linux host or container. If the target were actually vulnerable, the response would hand the attacker a working set of cloud credentials, with whatever permissions that AWS identity carries: S3 buckets, EC2, IAM, all of it.
Credential-file harvesting via injected shell commands is a staple of internet-wide scanning, and Siren sees variations of it constantly. What makes this capture worth writing up is the header sitting two lines above the payload.
| Property | Value |
|---|---|
| Target endpoint | /admin/config?cmd=cat+/root/.aws/credentials |
| Targets | Two Siren sensors (addresses masked), ports 80 and 443 |
| Claimed identity #1 | GPTBot/1.4 (OpenAI) |
| Claimed identity #2 | Amzn-SearchBot/1.0 (Amazon) |
| Request count | 3, identical payload |
Stage 2: Why Fake Being a Bot
A User-Agent string is not an identity. It is a single line of text a client sends to describe itself, and the server has no built-in way to verify it: there's no signature, no certificate, no handshake proving "I am actually OpenAI." Anyone can set that field to anything.
OpenAI and Amazon publish their crawler UA strings openly, precisely so site operators can allow or block them in robots.txt and firewall rules. That transparency is what makes the spoof possible: the exact string a defender needs to recognize a legitimate crawler is also the exact string an attacker needs to impersonate one.
Two things are being bought with that impersonation:
Blending into log noise. Legitimate AI crawler traffic is now a constant, high-volume presence in web server logs: GPTBot, Amazonbot, PerplexityBot, and others crawl at scale every day. A malicious scan wearing that same UA looks, at a glance, like one more entry in an already-long list of routine crawler visits.
Exploiting lazy allowlisting. Some WAFs and reverse proxies are configured to trust known-good bot names outright, skipping a rate limit, a challenge, or a security rule based on nothing but the UA string matching a known pattern. If that's the entire check, then typing the right string is the entire bypass. The correct way to verify a crawler is to check the source: reverse DNS on the connecting IP resolving back to the claimed company's domain, or matching against that company's published IP ranges, not the self-reported name in a header nobody signs.
That is the check that settles it. A genuine GPTBot or Amazonbot request comes from the ranges its operator publishes; a scanner borrowing the name comes from whatever cheap hosting it rented. The payload here already gives the game away, but the source check is what a WAF rule can enforce.
Stage 3: The Same Trick Against Paywalls, Not Just WAFs
The Siren capture is the malicious end of this story, but the same underlying weakness shows up in a much more mundane place: content gates.
Several major sites now allowlist AI agent UA strings for a different reason than security: they want AI assistants to read and cite their content, the same logic that once drove SEO investment in Googlebot. That's a reasonable business decision. The problem is that some of those sites apply looser rules to a claimed AI-agent UA than they apply to an ordinary logged-out browser, without ever confirming the request is actually coming from the AI company in question. A generic browser hits a login wall or a paywall stub; a request claiming to be an AI agent walks straight through, because the site is making an access decision based on a string, not a verified source.
That's the same root cause as the credential-hunting request above, just aimed at a paywall instead of /root/.aws/credentials. Wherever a UA string alone is treated as sufficient proof of identity, it will eventually be treated as sufficient proof by someone it wasn't meant to convince.
Putting the Chain Together
- Reconnaissance: two sensors receive an identical command-injection payload against a fake
/admin/configendpoint. - Identity claim: each request's User-Agent header self-identifies as
GPTBot/1.4orAmzn-SearchBot/1.0, with no verification mechanism backing the claim. - Exploitation attempt: the
cmdparameter tries to forcecat /root/.aws/credentials, aiming to exfiltrate AWS access keys. - Defense evasion: the spoofed UA is built to blend into high-volume legitimate crawler traffic and to exploit UA-based allowlisting where it exists.
- Behavior mismatch: a command-injection payload aimed at an AWS credentials file is not crawler behavior, so the identity claim is false.
- Detection: Siren flagged the request on payload behavior alone, independent of the claimed crawler identity.
The spoof itself costs the attacker nothing, it's one string in a header. What it buys is a chance at blending into log noise and, on some targets, a chance at bypassing UA-based allowlisting outright.
Indicators of Compromise
Network indicators
| Indicator | Context |
|---|---|
/admin/config?cmd=cat+/root/.aws/credentials |
Command-injection payload targeting AWS credential path |
Spoofed identity indicators
| Claimed identity | Header string used |
|---|---|
| GPTBot (OpenAI) | Mozilla/5.0 AppleWebKit/537.36 (KHTML, like Gecko; compatible; GPTBot/1.4; +https://openai.com/gptbot) |
| Amazonbot | Mozilla/5.0 (compatible; Amzn-SearchBot/1.0; +https://developer.amazon.com/support/amazonbot) |
A claimed crawler identity should always be checked against the operator's published IP ranges. A mismatch is the tell, and here the payload makes the claim false on its own.
What to Do About It
- Never authorize traffic on UA string alone. If a request claims to be GPTBot, Amazonbot, or any other named crawler, verify it against the company's published IP ranges or via reverse DNS lookup on the source before granting it any elevated trust, whether that's reduced rate limiting, skipped WAF rules, or paywall bypass.
- Treat UA-claimed-crawler plus suspicious payload as an aggravating signal, not a mitigating one. A request that mismatches its claimed identity against its actual behavior deserves more scrutiny, not less.
- Alert on requests for well-known credential paths regardless of source.
/root/.aws/credentials,.env,id_rsa, and similar paths appearing anywhere in a query string or request body are a strong, cheap signal independent of headers. - Log the mismatch itself. A UA claiming GPTBot from a source IP that isn't in OpenAI's published ranges is, on its own, worth flagging: evidence of intent to impersonate, even on requests that turn out to be otherwise harmless.
- Audit existing allowlist rules. Review WAF and reverse-proxy configurations for any rule that grants reduced scrutiny based on UA string matching alone, and replace string-based crawler checks with IP-range or reverse-DNS validation.
Closing Thoughts
None of the individual pieces here are new. Credential harvesting through injected commands has been standard opportunistic-scanner behavior for years, and UA spoofing has existed for exactly as long as the User-Agent header has. What's changed is the cover available: a year ago, claiming to be "Googlebot" was the default disguise, easily flagged since Googlebot's traffic patterns and IP ranges are heavily scrutinized. Today, a growing list of AI crawlers, each with its own published UA string and each generating a legitimate and growing volume of real traffic, gives an attacker more names to borrow and more background noise to hide inside.
The fix isn't new either: verify identity at the network layer, not the header layer. A name typed into a request is not a credential. Until more of the internet's access-control logic catches up to that, the crawler war between publishers and AI companies will keep producing exactly this kind of collateral cover for attackers wearing someone else's name.
Related reading from Cypho: